ZAI Language
GLM-5.3-Flash
Natively multimodal coding model with 1M context at flash-tier pricing.
About
GLM-5.3-Flash is the first natively multimodal model in Z.ai's GLM-5 series, a 320B-parameter Mixture-of-Experts design that activates 18B per token. A hybrid attention architecture pairs linear attention for local context with sparse attention and a lightweight indexer for global retrieval, cutting long-context serving cost across its 1M-token window. Trained on a 30T-token multimodal corpus, it reads images, video, and documents alongside code and lands close to flagship-class results on agentic coding benchmarks at a fraction of the price.
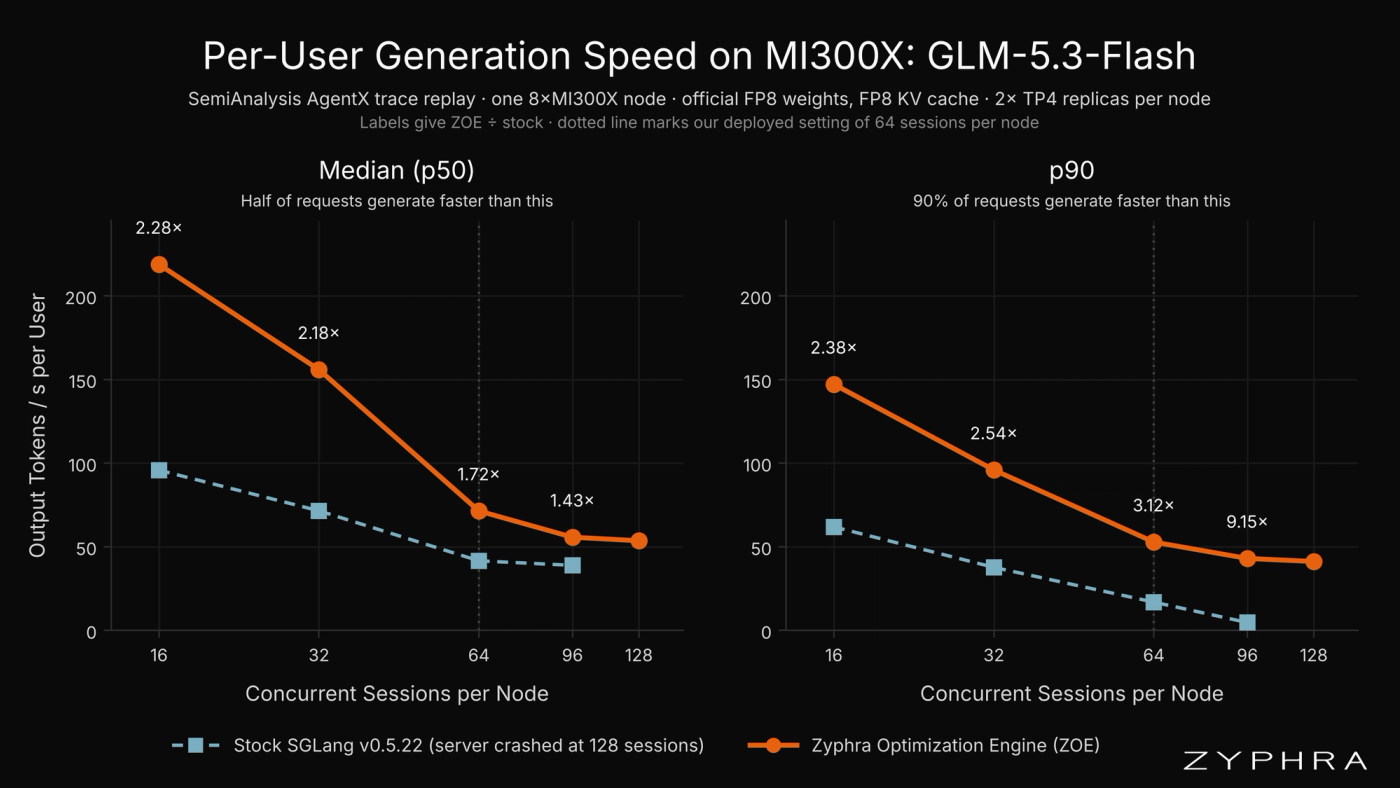
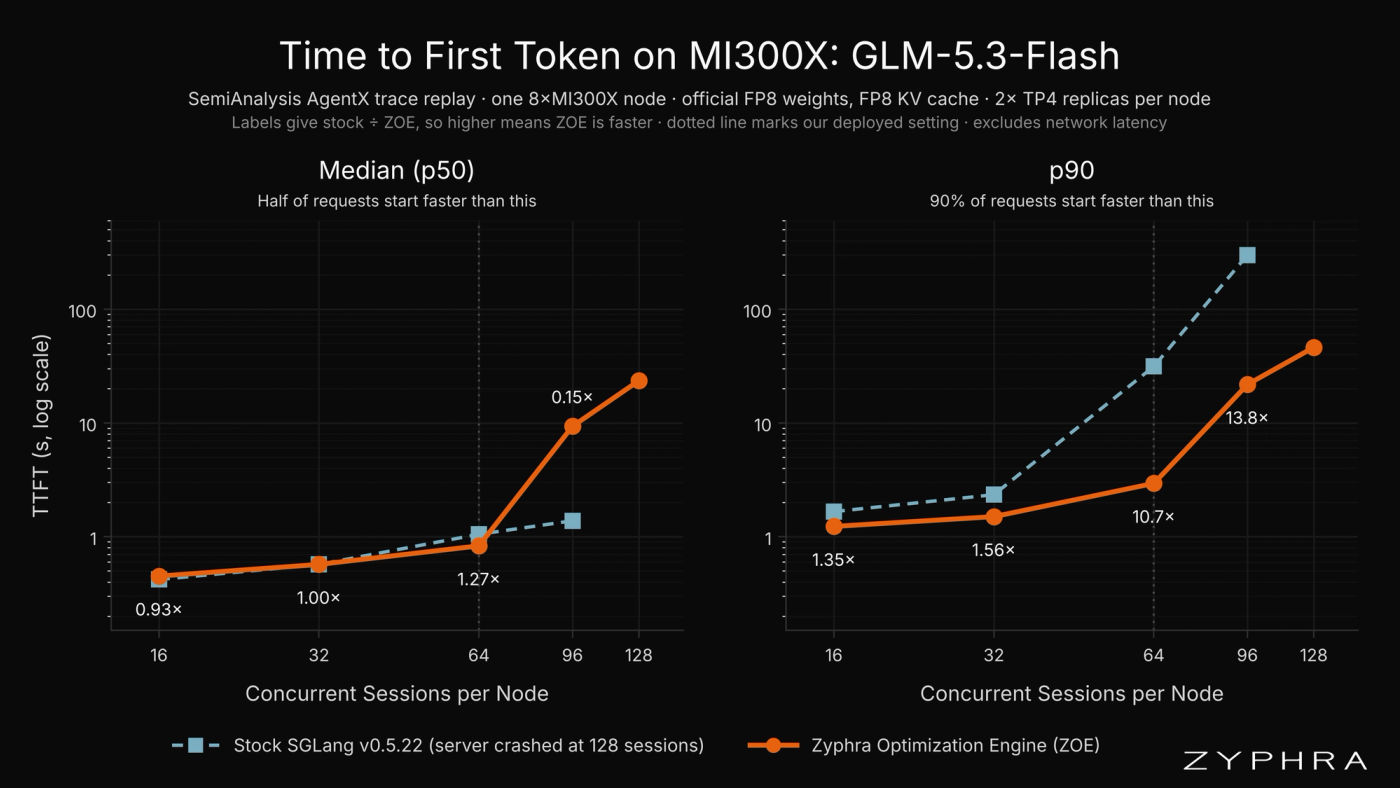
Performance Benchmarks on Zyphra Inference with Zyphra Optimization Engine
We compared ZOE with stock SGLang on one 8xMI300X node using SemiAnalysis AgentX (a replay of multi-turn coding agent sessions).
API usage
import os
from openai import OpenAI

client = OpenAI(
    api_key=os.getenv("ZYPHRA_API_KEY"),
    base_url="https://api.zyphracloud.com/api/v1",
)

response = client.chat.completions.create(
    model="zai-org/GLM-5.3-Flash",
    messages=[{"role": "user", "content": "Hello!"}],
)

print(response.choices[0].message.content)
import OpenAI from "openai";
const client = new OpenAI({
apiKey: process.env.ZYPHRA_API_KEY,
baseURL: "https://api.zyphracloud.com/api/v1",
});
const response = await client.chat.completions.create({
model: "zai-org/GLM-5.3-Flash",
messages: [{ role: "user", content: "Hello!" }],
});
console.log(response.choices[0].message.content);curl https://api.zyphracloud.com/api/v1/chat/completions \
-H "Authorization: Bearer $ZYPHRA_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"model": "zai-org/GLM-5.3-Flash",
"messages": [{"role": "user", "content": "Hello!"}]
}'