Scaling Subquadratic Attention to Trillions of Parameters
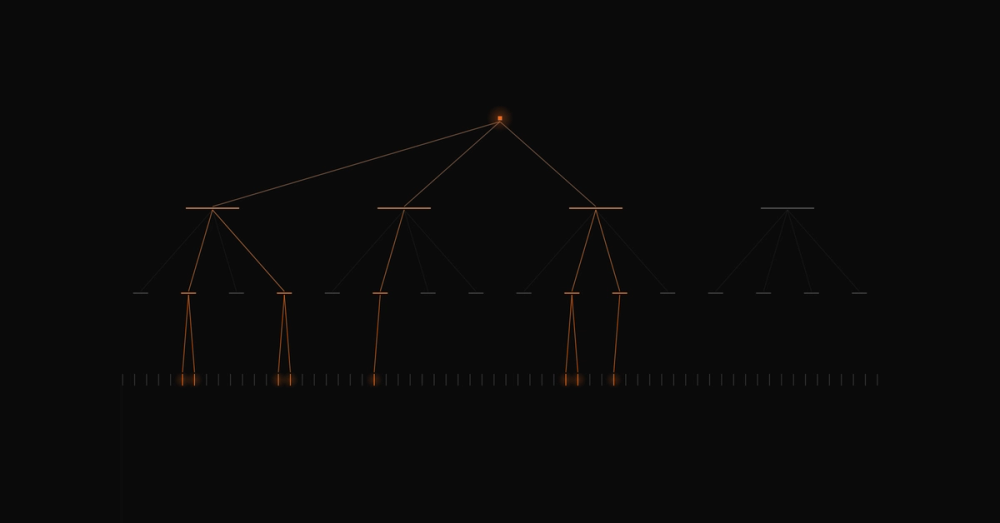
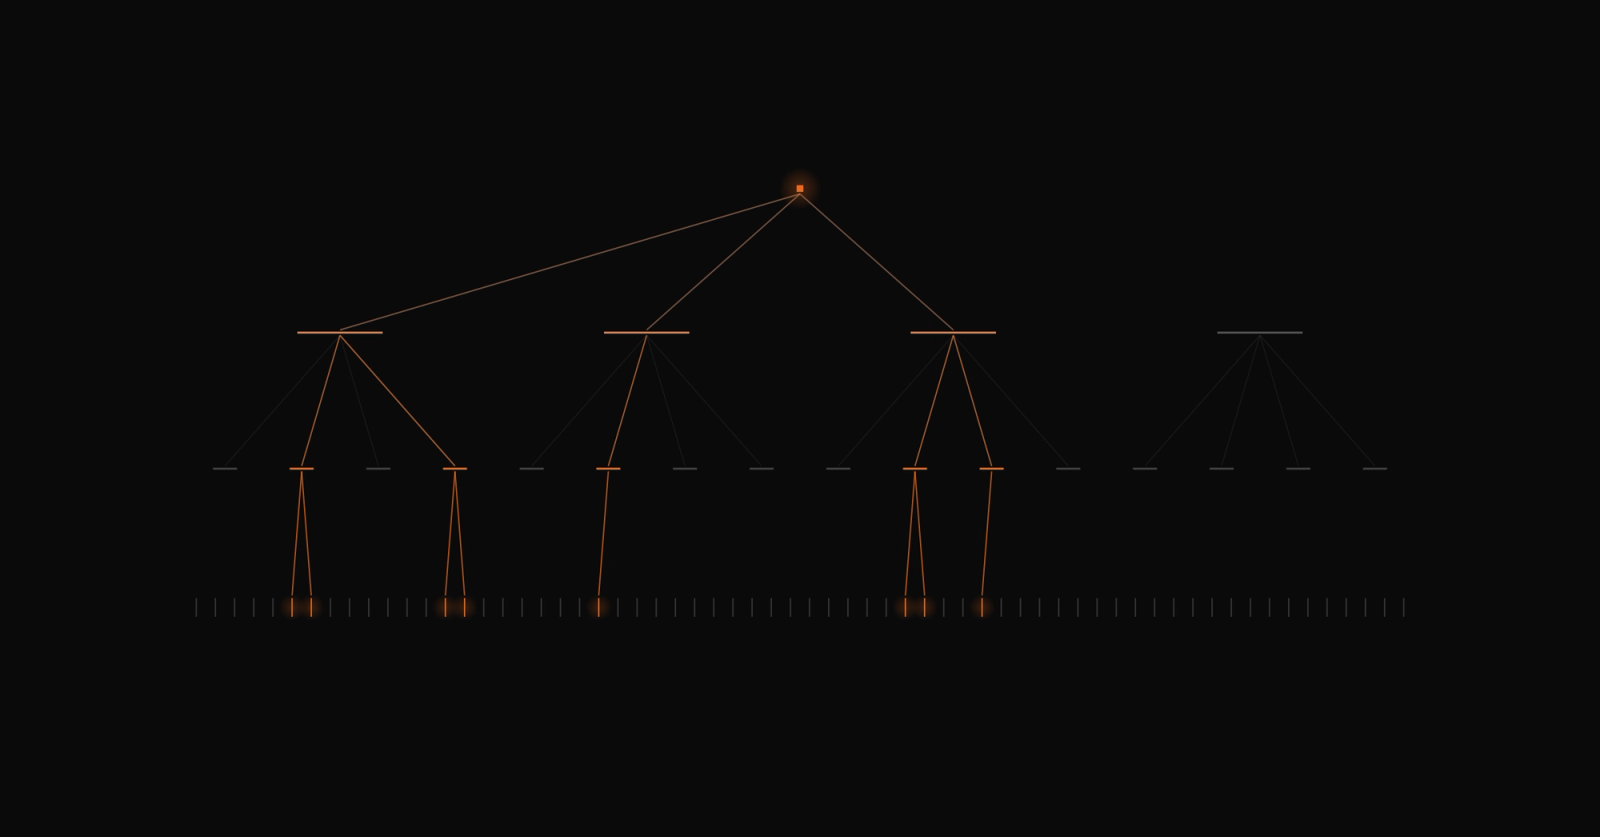
We recently introduced Zyphra Hierarchical Attention (ZHA; see paper and blog), a subquadratic attention method that uses a tree of compressed KV-cache summaries to efficiently retrieve relevant information from arbitrarily long contexts. We demonstrated that ZHA could be applied to existing pretrained language models through an unusually inexpensive distillation procedure, preserving performance on challenging reasoning, retrieval, and agentic benchmarks. In contrast to other sparse attention methods like DSA, MSA, or QSA that produce a constant-factor speedup, our ZHA adds tree depth (with demonstrated performance retention up to 6 levels) as sequence length increases, which in combination with our top-p selection mechanism enables truly subquadratic computational scaling of attention. However, our initial experiments were limited to models in the 30B parameter range. Here, we scale ZHA to some of the largest and most capable open-weight models available, including Qwen3.8-2.4T-A95B, Nemotron-3.5-Super, and MiMo-V2.6-Pro. We find that ZHA conversion continues to work remarkably well at scale, generally preserving model capabilities with little or no degradation, including on challenging long-context evaluations (e.g., we observe less than 2% degradation on 1M RULER for Qwen). However, the computational scaling of ZHA depends critically on the underlying structure of the model's attention distributions. We find consistently clean sublinear power-law scaling in Qwen, while other architectures exhibit more complicated behavior, including approximately uniform attention distributions in the first few layers and anomalous long-context scaling. These results suggest that the principal obstacle to truly subquadratic attention at frontier scale may not be the sparse attention algorithm itself, but the ability to train sufficiently well-structured attention distributions in the underlying model backbone.
Read the post